Noisy (@noisyb0y1)
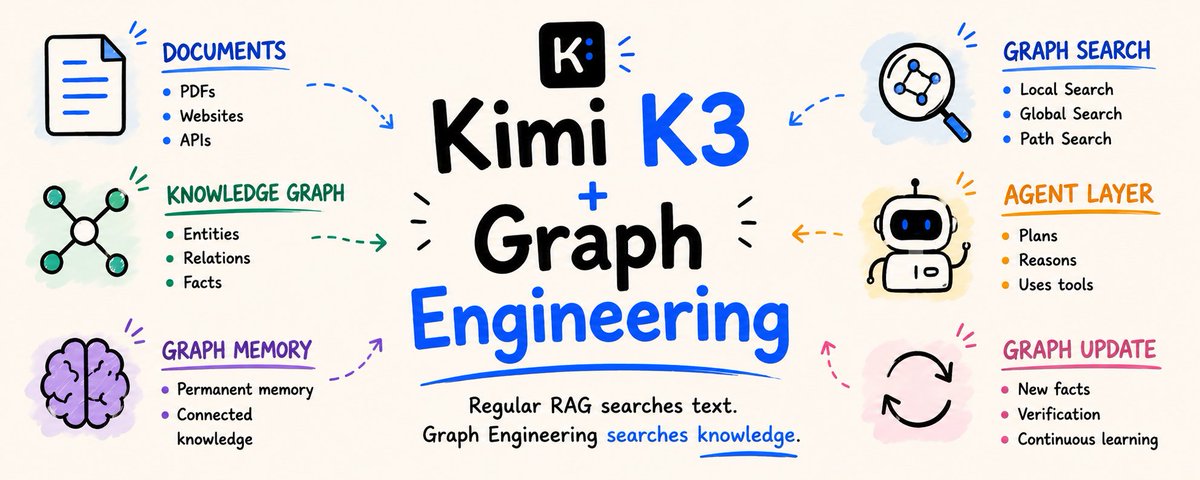
Most people use AI like an expensive search engine. Open a chat, ask a question, get an answer, close the tab. Next day they start from zero because the AI remembers nothing.
But there are developers making $10,000-20,000 a month simply because their AI system responds twice as fast, gives more accurate answers and costs 85% less than their competitors. They're not using some secret model. They built the right architecture around a regular model.
It's called Kimi K3 + Graph Engineering. Microsoft spent years proving it works - 85% lower costs, 18% better accuracy.
Here's how to build this yourself from scratch in a week.
Why regular RAG stops working at some point
Most developers build AI systems the same way. User asks something, the system searches through documents, finds similar text fragments, model generates an answer. Works fine for simple questions. Falls apart completely for complex ones.
Ask "why did our sales drop in March?" and regular RAG finds documents with the words "sales" and "March." It finds fragments. It doesn't find the chain of causes.
Regular RAG answer:
Here are 5 documents mentioning sales in March.

Graph Engineering answer:
Sales dropped because of a release delay
caused by a supplier problem
triggered by a warehouse failure
which generated negative reviews
which reduced conversion by 23%.
Same model. Same data. Completely different result - because one system searches text and the other searches connections between real facts.
This is what Microsoft, Stanford and Anthropic all independently figured out. And it's why the developers who understand this are moving faster than everyone else.
What a knowledge graph actually is
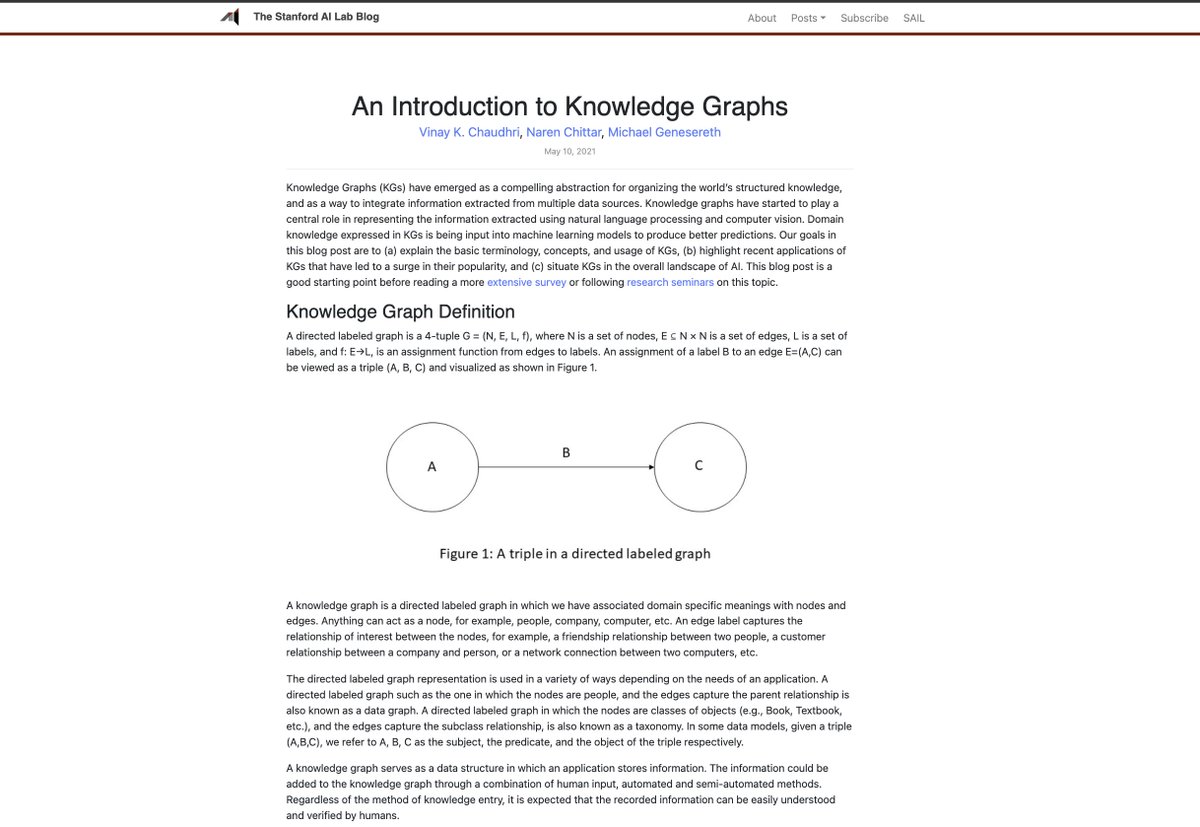
A knowledge graph stores information as triples:
Subject → Relation → Object
Real examples:
Kimi K3       → developed by     → Moonshot AI
Kimi K3       → context window   → 1 million tokens
Microsoft     → built            → GraphRAG
GraphRAG      → reduces costs by → 85%
Anthropic     → created          → Claude
Claude        → supports         → MCP
Every piece of information is an explicit connection between two entities. Not a paragraph of text that might contain this information somewhere - a structured fact you can query directly.
Regular database:
Table of companies
Table of products
No explicit connections between them

Knowledge graph:
Company → created → Product
Product → competes with → Other Product
Other Product → owned by → Other Company
Company → invested in → Other Company
The graph doesn't just store facts. It stores how facts connect to each other. That's what makes complex reasoning possible - and what regular RAG can never do no matter how good the model is.
Stanford AI Lab defines a knowledge graph as a structured database where information is represented as a network of entities and relationships in subject-relation-object triples. Used in search, recommendations and tasks where you need to find indirect connections.
ai.stanford.edu/blog/introduction-to-knowledge-graphs
Why Kimi K3 is the right model for this architecture
Most models have 128,000-200,000 token context windows. Kimi K3 has one million. This isn't just an impressive number - it's an architectural advantage specifically for Graph Engineering.
A graph returns subgraphs, chains of evidence, lists of connected entities. All of this takes up space in the context window. With a small context you have to cut the graph. With one million tokens the entire relevant part of the graph fits in one session.
Kimi K3 architecture:
2.8 trillion total parameters
896 experts in MoE, 16 active per token
1,048,576 token context window
Native image analysis
Kimi Delta Attention for long sequences
Attention Residuals for preserving signals between layers
kimi.com/blog/kimi-k3
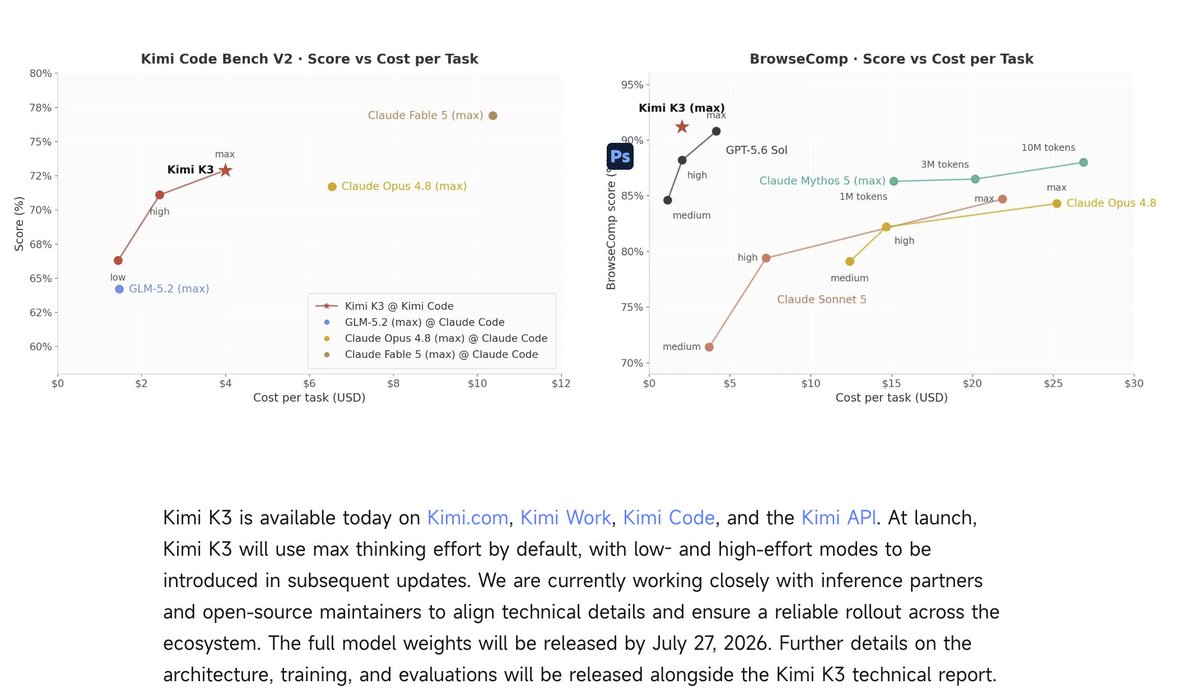
Kimi Delta Attention is a hybrid mechanism that reduces the cost of working with long sequences. For Graph Engineering this means the system can pass the model large subgraphs, long evidence lists, dozens of documents and repository structure without catastrophic cost increases.
But even one million tokens is temporary memory. After the session everything disappears.
1M token context   =  large working surface per session
Knowledge graph    =  permanent structured memory between sessions
Kimi K3 gives scale and reasoning. Graph Engineering gives memory and structure. Together they solve different problems at the same time.
Document 1 - Microsoft GraphRAG
github.com/microsoft/graphrag
arxiv.org/abs/2603.22528
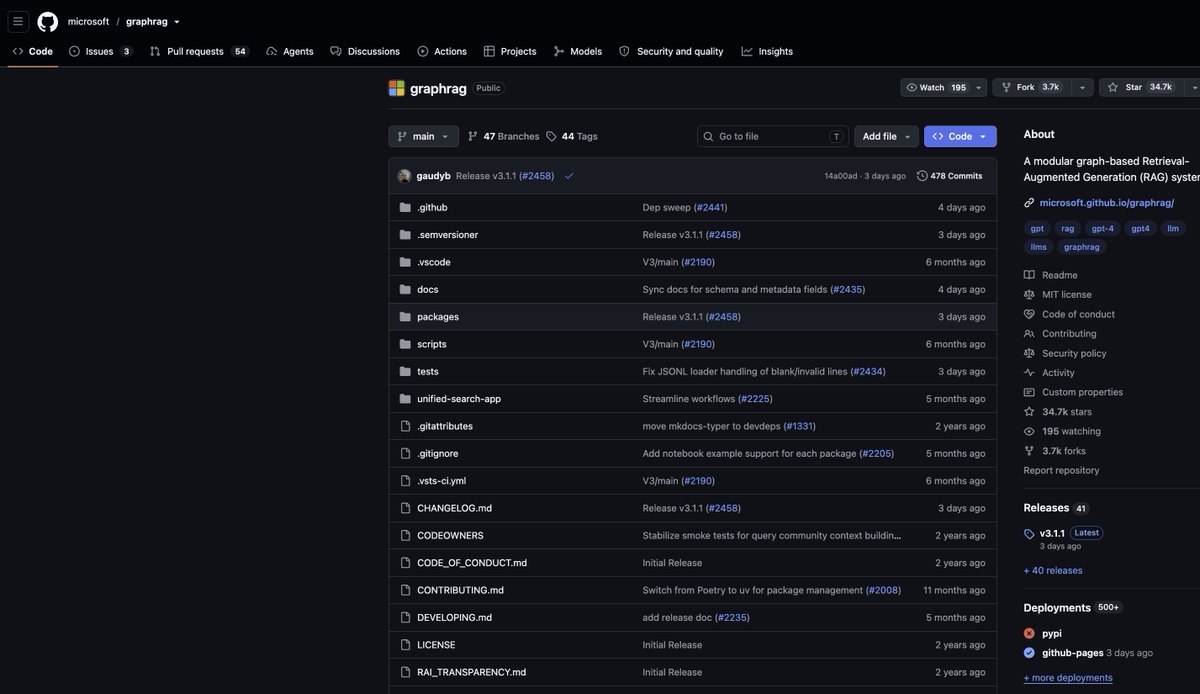
Microsoft built GraphRAG and open-sourced it. The numbers from their research are the most concrete evidence available for what Graph Engineering actually delivers versus regular RAG.
The architecture converts unstructured text into a full knowledge graph:
Load documents
↓
Chunk documents
↓
Extract entities and relations
↓
Build graph
↓
Detect communities
↓
Generate community reports
↓
Embed entities and reports
↓
Local Search / Global Search
Key insight from Microsoft: regular RAG answers local questions well - find information about this specific entity. It fails on global questions - what are the main patterns across these 10,000 documents, what connects these events across the entire dataset.
Graph Engineering answers both.
Local Search   |  what happened with supplier X in March
               |  finds specific node and its connections

Global Search  |  what are the main risk patterns
               |  across all our supplier relationships
               |  finds patterns across the entire graph
Real numbers from the ChatP&ID research:
Accuracy improvement      |  18% higher than raw document approach
Token cost reduction      |  85% lower than loading structured files directly
Cost per task             |  approximately $0.004 in tested configuration
Document 2 - Three modes of combining LLM and Knowledge Graph
arxiv.org/abs/2306.08302
One of the strongest theoretical papers on combining language models and knowledge graphs describes three modes:
Mode 1 - KG-enhanced LLM
Graph gives the model facts and structure
Model generates better answers

Mode 2 - LLM-augmented KG
Model creates, cleans and expands the graph
Graph gets better over time

Mode 3 - Synergized LLM + KG
Graph and model improve each other mutually
Most powerful mode
For Kimi K3 + Graph Engineering the third mode works best. Kimi K3 extracts new facts and adds them to the graph. The graph gives Kimi K3 structured context for reasoning. The cycle repeats and the system gets better with every iteration.
Document 3 - Relational Memory for language models
direct.mit.edu/tacl/article/doi/10.1162/tacl_a_00476
MIT Press, Transactions of the Association for Computational Linguistics.
The research shows what happens when you connect a language model to relational memory - a knowledge graph of relationships instead of text fragments.
Text context
↓
Extract relevant relations from graph
↓
Relational Memory
↓
Language model
↓
More coherent and accurate generation
Key finding: models with access to explicit relationship structures produce more coherent text and make fewer logical errors than models working from text alone.
This is the scientific explanation for why Graph Engineering works. The model doesn't have to infer relationships from text. The relationships are explicit in the graph. The model uses them directly.
Published under CC BY 4.0 - can be freely used with attribution.
Document 4 - Scaling Laws for Knowledge Graph Engineering
arxiv.org/abs/2505.16276
Research that compared 26 open-source models on knowledge graph engineering tasks. The conclusion is one of the most important findings in the field:
Larger model + bad graph   |  worse results
Smaller model + good graph |  better results
The right graph beats the bigger model. Every time.
Same conclusion Microsoft reached with GraphRAG and Anthropic reached with Claude Code - the system around the model determines the output more than the model itself. Graph Engineering is the most concrete implementation of that principle.
Document 5 - Agent-as-a-Graph
arxiv.org/abs/2511.18194
This paper shows how to represent not just knowledge but agents and tools as nodes in a graph.
User question
↓
Graph of capabilities
↓
Select research agent
↓
Select GitHub tool
↓
Select ArXiv tool
↓
Select graph database tool
↓
Kimi K3 coordinates execution
Authors report Recall@5 improvement of 14.9% and nDCG@5 improvement of 14.6% versus comparable retrievers on LiveMCPBenchmark.
For Kimi K3 this means the graph can manage not just knowledge but which agent and which tool to use for each specific task.
Document 6 - Kimi Code and Agent SDK
github.com/MoonshotAI/kimi-code
github.com/MoonshotAI/kimi-agent-sdk
Kimi Code is a terminal agent that can:
Read and edit code
Run shell commands
Search files
Fetch web pages
Analyze the result of each step
Independently choose the next action
Supports MCP
Lifecycle hooks
Approval modes
Kimi Agent SDK lets you use Kimi Code as the foundation of your own agent. It reuses the tools, skills and MCP server configuration from Kimi Code.
For Graph Engineering this is a ready-made execution layer. The graph provides structured knowledge and reasoning paths. Kimi Code takes actions in the real environment. The SDK ties everything together.
The full system architecture
Step 1 - Ingestion Layer
PDFs, websites, databases, APIs, Slack, Notion
↓

Step 2 - Extraction Layer
Kimi K3 extracts entities and relationships

{
  "entity": "Kimi K3",
  "type": "AI model",
  "relations": [
    {
      "predicate": "developed_by",
      "object": "Moonshot AI",
      "confidence": 0.98
    }
  ]
}

↓

Step 3 - Resolution Layer
System resolves whether these are the same entity:
Moonshot AI / Moonshot / Beijing Moonshot / 月之暗面

↓

Step 4 - Graph Storage
Neo4j / Memgraph / Amazon Neptune / PostgreSQL

↓

Step 5 - Retrieval Layer
Vector search + Entity lookup + Path search
Community search + Temporal filtering

↓

Step 6 - Agent Layer
Kimi K3:
Plans the approach
Chooses the right tool
Generates Cypher or SPARQL queries
Analyzes subgraph
Runs web research
Draws conclusions
Identifies the next knowledge gap

↓

Step 7 - Verification Layer
Checks evidence coverage
Finds contradictions
Evaluates confidence
Verifies sources

↓

Step 8 - Graph Update
New facts added to graph
Contradictions flagged
Old information gets timestamp
This is a closed knowledge-action loop. Kimi K3 doesn't just read the graph. It identifies what's missing, forms sub-questions, selects a node or subgraph, runs a search, checks the result, adds a new fact and re-evaluates the hypothesis.
Five prompts that run the entire pipeline
Graph Engineering doesn't replace prompts. It uses them at each specific stage.
Prompt 1 - Extraction
Extract all organizations, people, products and events.

For each entity return:
- canonical_name
- type
- description
- source

For each relationship return:
- source_entity
- relation_type
- target_entity
- evidence
- confidence_score
Prompt 2 - Normalization
Compare the following entities.
Determine whether they refer to:
- the same entity
- related but different entities
- unrelated entities

Return canonical name and explanation.
Do not merge entities without clear evidence.
Prompt 3 - Graph Query
Translate the user question into a Cypher query.
Use only relationships present in the schema.
Do not invent labels or properties.
Return the query and explanation of the logic.
Prompt 4 - Grounded Answer
Answer using only the retrieved graph paths.
For every conclusion:
- identify the supporting nodes
- identify the relationship path
- state uncertainty clearly
- do not infer causation from correlation
Prompt 5 - Graph Maintenance
Compare new facts with the existing graph.
Classify each fact as:
- new
- duplicate
- contradiction
- update
- uncertain

Do not overwrite existing facts without evidence.
Five businesses you can build on this system
1 - Investment Research
Company
├── founders and their previous projects
├── investors and their portfolio
├── competitors and their strategies
├── legal risks
├── patents
├── job openings as strategy signal
└── financial metrics over time
Kimi K3 reads reports and news. The graph shows hidden connections between companies, shared investors, supplier dependencies and personnel signals. Clients: investment funds, law firms, M&A consultants. $2,000-10,000 per client per month.
2 - Engineering Intelligence
GitHub commits + Jira tickets + Linear tasks
↓
Graph of Engineering Work
↓
5x faster incident detection
50% less meeting time
Automatic release notes
anthropic.com/customers/graph
LaunchNotes already sells this. The market is every engineering team using more than one project management tool.
3 - Scientific Research Engine
Paper → author → institution → method → dataset → result
↓
Which GraphRAG methods use community detection,
on which datasets they were tested
and which papers contradict each other
Regular search gives a list of documents. A graph system builds a map of evidence and contradictions.
4 - Cybersecurity Threat Graph
IP → domain → certificate → malware → campaign → actor
↓
Kimi K3 analyzes threat reports
Maps indicators across sources
Explains attack paths
Updates threat graph automatically
5 - Personal Knowledge OS
People ↔ Meetings ↔ Projects ↔ Documents ↔ Decisions ↔ Promises
↓
Questions Kimi K3 can answer:
Who is blocking this task?
What decision did we make and what was it based on?
What did I promise to do this month?
Which old assumptions are no longer valid?
Where to start this week
Day 1  |  install Neo4j locally
       |  read DSPy README
       |  github.com/stanfordnlp/dspy
       |  understand the difference between prompting
       |  and programming a system

Day 2  |  take one set of documents
       |  run Kimi K3 via API
       |  extract first entities and relationships
       |  save to Neo4j

Day 3  |  build first retrieval layer
       |  combine vector search and graph search
       |  test on a complex question RAG can't answer

Day 4  |  connect Kimi Code via MCP
       |  github.com/MoonshotAI/kimi-code
       |  let the agent read the graph and add new facts
       |  run first knowledge-action loop

Day 5  |  measure the result
       |  compare accuracy vs regular RAG
       |  compare token costs
       |  find first real client use case
What Microsoft, Stanford and Anthropic figured out together
Microsoft GraphRAG    |  graph cuts costs 85%, improves accuracy 18%
Stanford DSPy         |  model is a node in a graph, not the center
Stanford Scaling Laws |  smaller model + good graph beats bigger model
MIT Press Research    |  explicit relationships improve coherence and accuracy
Anthropic LaunchNotes |  5x faster incident detection, 50% less meeting time
Kimi K3 is the engine. Graph Engineering is the map, the memory and the coordinate system. Without the engine the graph doesn't act. Without the graph the engine moves very fast but doesn't always know where it's going.
Most developers will keep building regular RAG and wonder why complex questions give bad answers. A few will spend a week building a graph system and never go back to searching text.
You build your own life - so choose the right path.
/ If this was useful - follow /
💬 13 🔁 25 ❤️ 193 👁️ 148.9K
View full thread
About author
Noisy
DEV 4 yrs exp, X enjoyer
📌 X 📆 2022-09-14
769 Following 23K Followers 22.6K Posts
View full thread